Vynaris
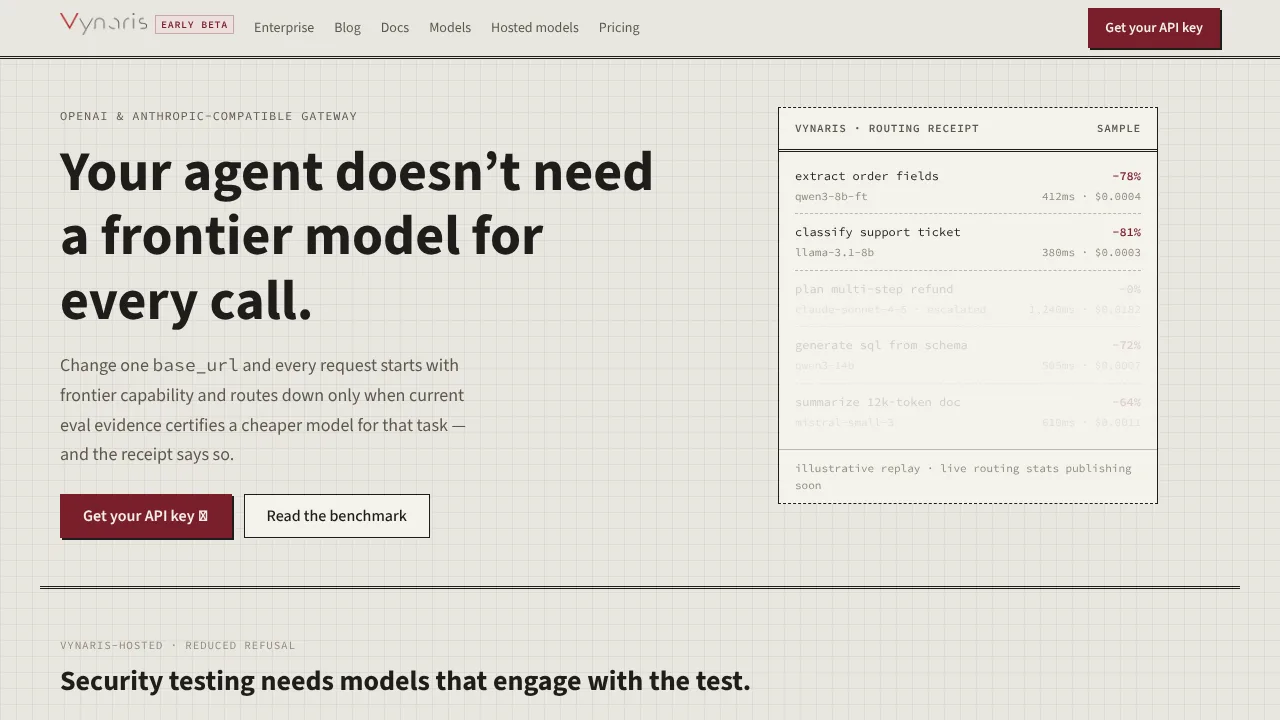
Vynaris is an OpenAI- and Anthropic-compatible inference gateway that automatically routes requests to cheaper models while maintaining quality and returning detailed transparent cost receipts.
Official website(opens in new tab)OfficialChecked
Evidence-backed listing facts
Only known values with retained provenance are shown. Missing fields are omitted instead of being filled with guesses.
- Product form Verified
- Infrastructure service
Evidence: The inference gateway that shows its receipts. Right-sized models, transparent costs, one base URL.
Official website(opens in new tab)OfficialChecked
- Primary job Verified
- Developer infrastructure
Evidence: Vynaris is an OpenAI-compatible chat completions gateway at https://api.vynaris.com /v1 .
Official documentation(opens in new tab)OfficialChecked
- Pricing Verified
- Usage based
Evidence: Usage is billed at the original provider pricing plus a convenience fee: 3% on your first $500 of usage each calendar month, then 1%.
Official pricing(opens in new tab)OfficialChecked
- Deployment Verified
- Cloud
Evidence: Vynaris-hosted · reduced refusal
Official website(opens in new tab)OfficialChecked
- Interfaces Verified
- API
Evidence: Vynaris is an OpenAI-compatible chat completions gateway at https://api.vynaris.com /v1 .
Official documentation(opens in new tab)OfficialChecked
- API Verified
- Public API
Evidence: GET /v1/ping — verifies connectivity and that the key is valid. Returns quickly with no charge.
Official documentation(opens in new tab)OfficialChecked
Reviewed sources
These sources were reachable when the listing evidence was checked.
Listing checked
About Vynaris
Vynaris is an OpenAI- and Anthropic-compatible inference gateway that automatically routes requests to cheaper models while maintaining quality and returning detailed transparent cost receipts.
Evidence: Change one base_url and every request starts with frontier capability and routes down only when current eval evidence certifies a cheaper model for that task — and the receipt says so.
Official website(opens in new tab)OfficialChecked
It features hosted, private, scale-to-zero model variants designed for lawful security testing and red teaming without prompt or output retention.
Evidence: Select a hosted Qwen or DeepSeek variant directly in the request. Get 128K context, published per-token pricing, private scale-to-zero capacity, and no prompt or output retention. Built for…
Official website(opens in new tab)OfficialChecked
Capabilities
Single-endpoint integration allows developers to drop in the Vynaris gateway by swapping the SDK base URL.
Evidence: Swap the base URL in whatever client you already use, keep your prompts and tool definitions, and read the receipt on every response.
Official documentation(opens in new tab)OfficialChecked
Automatic escalation routes requests back up to the requested model if a smaller model does not meet quality standards.
Evidence: When small models aren’t good enough, we route up to the model you asked for and the receipt reads −0% .
Official website(opens in new tab)OfficialChecked
Hosted uncensored model options provide private capacity for security evaluations.
Evidence: Select a reduced-refusal model per request. Use the normal OpenAI-compatible chat completions endpoint and put one of the exact IDs below in model .
Official documentation(opens in new tab)OfficialChecked
Prepaid balance model where credits roll over, with no overage charges.
Evidence: Unused credit rolls over, top-ups still work, and usage stops at a zero balance—there are no overage charges.
Official pricing(opens in new tab)OfficialChecked
Use cases
Reducing inference costs for automated AI agents and tool-calling workloads.
Evidence: Vynaris exists because our own agent workloads were burning frontier-model tokens on tool calls a 8B model handles fine.
Official website(opens in new tab)OfficialChecked
Conducting lawful, authorized red teaming and security testing on system prompts and models.
Evidence: Built for lawful, authorized red teaming, defensive engineering, and model evaluation.
Official website(opens in new tab)OfficialChecked
Who Vynaris fits — and what to check
Decision guidance below is tied to the cited evidence. Treat observed third-party claims as leads, not product guarantees.
Best for
Developers and teams running heavy AI agent workloads who want to optimize token costs with per-request auditability.
Evidence: Built by heavy users, for their own bills first. Vynaris exists because our own agent workloads were burning frontier-model tokens on tool calls a 8B model handles fine.
Official website(opens in new tab)OfficialChecked
Limitations to check
Vynaris's native Anthropic wire format (/v1/messages) is not yet implemented, requiring Anthropic traffic to route through the OpenAI-compatible endpoint.
Evidence: Note: Vynaris’s native /v1/messages wire format is not yet implemented — route Anthropic-shaped traffic through the OpenAI-compatible /v1/chat/completions endpoint documented above until…
Official documentation(opens in new tab)OfficialChecked
First requests to private hosted models after an idle period may experience latency while capacity starts.
Evidence: The first request after an idle period can take longer while private capacity starts and model weights load.
Official documentation(opens in new tab)OfficialChecked
Method: ClawSites keeps discovery copy separate from publishable claims, retains a source excerpt, and displays the date each cited source was checked. Pricing and availability can still change after that date.
Related to Vynaris
Similar directory context, not an editorial claim that these products are interchangeable.
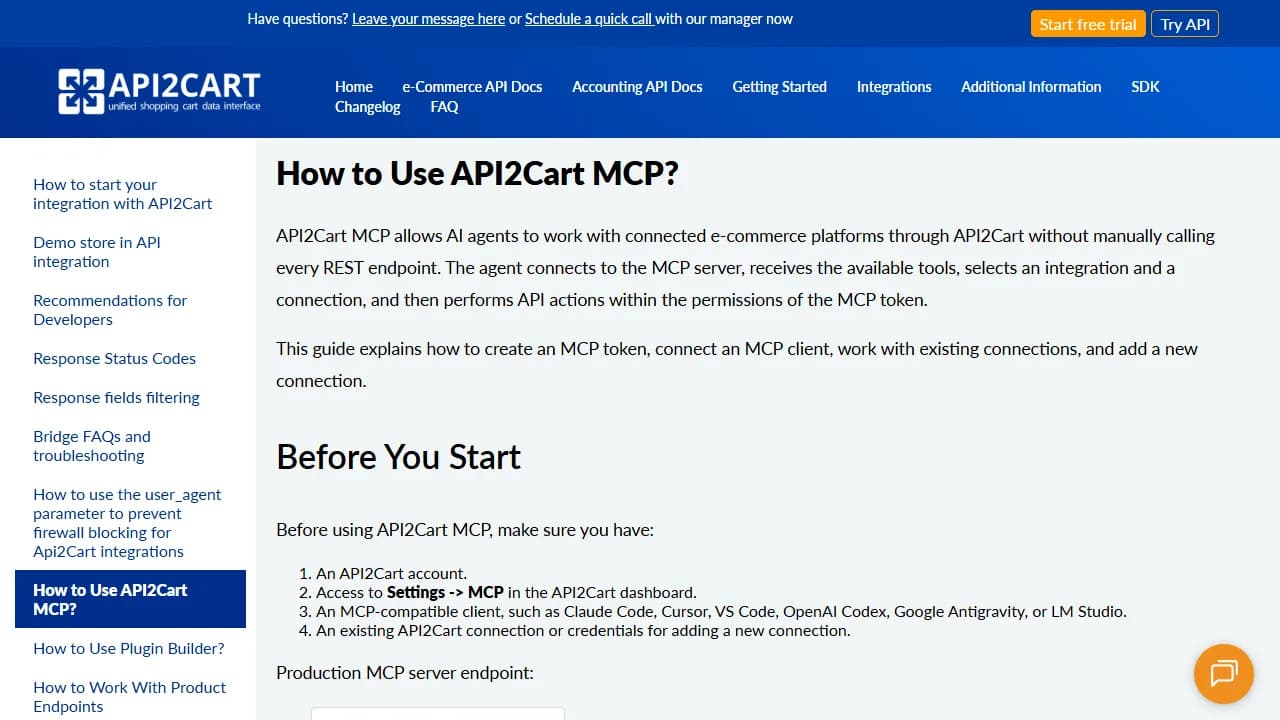
API2Cart MCP lets AI agents work with connected e-commerce platforms through API2Cart.
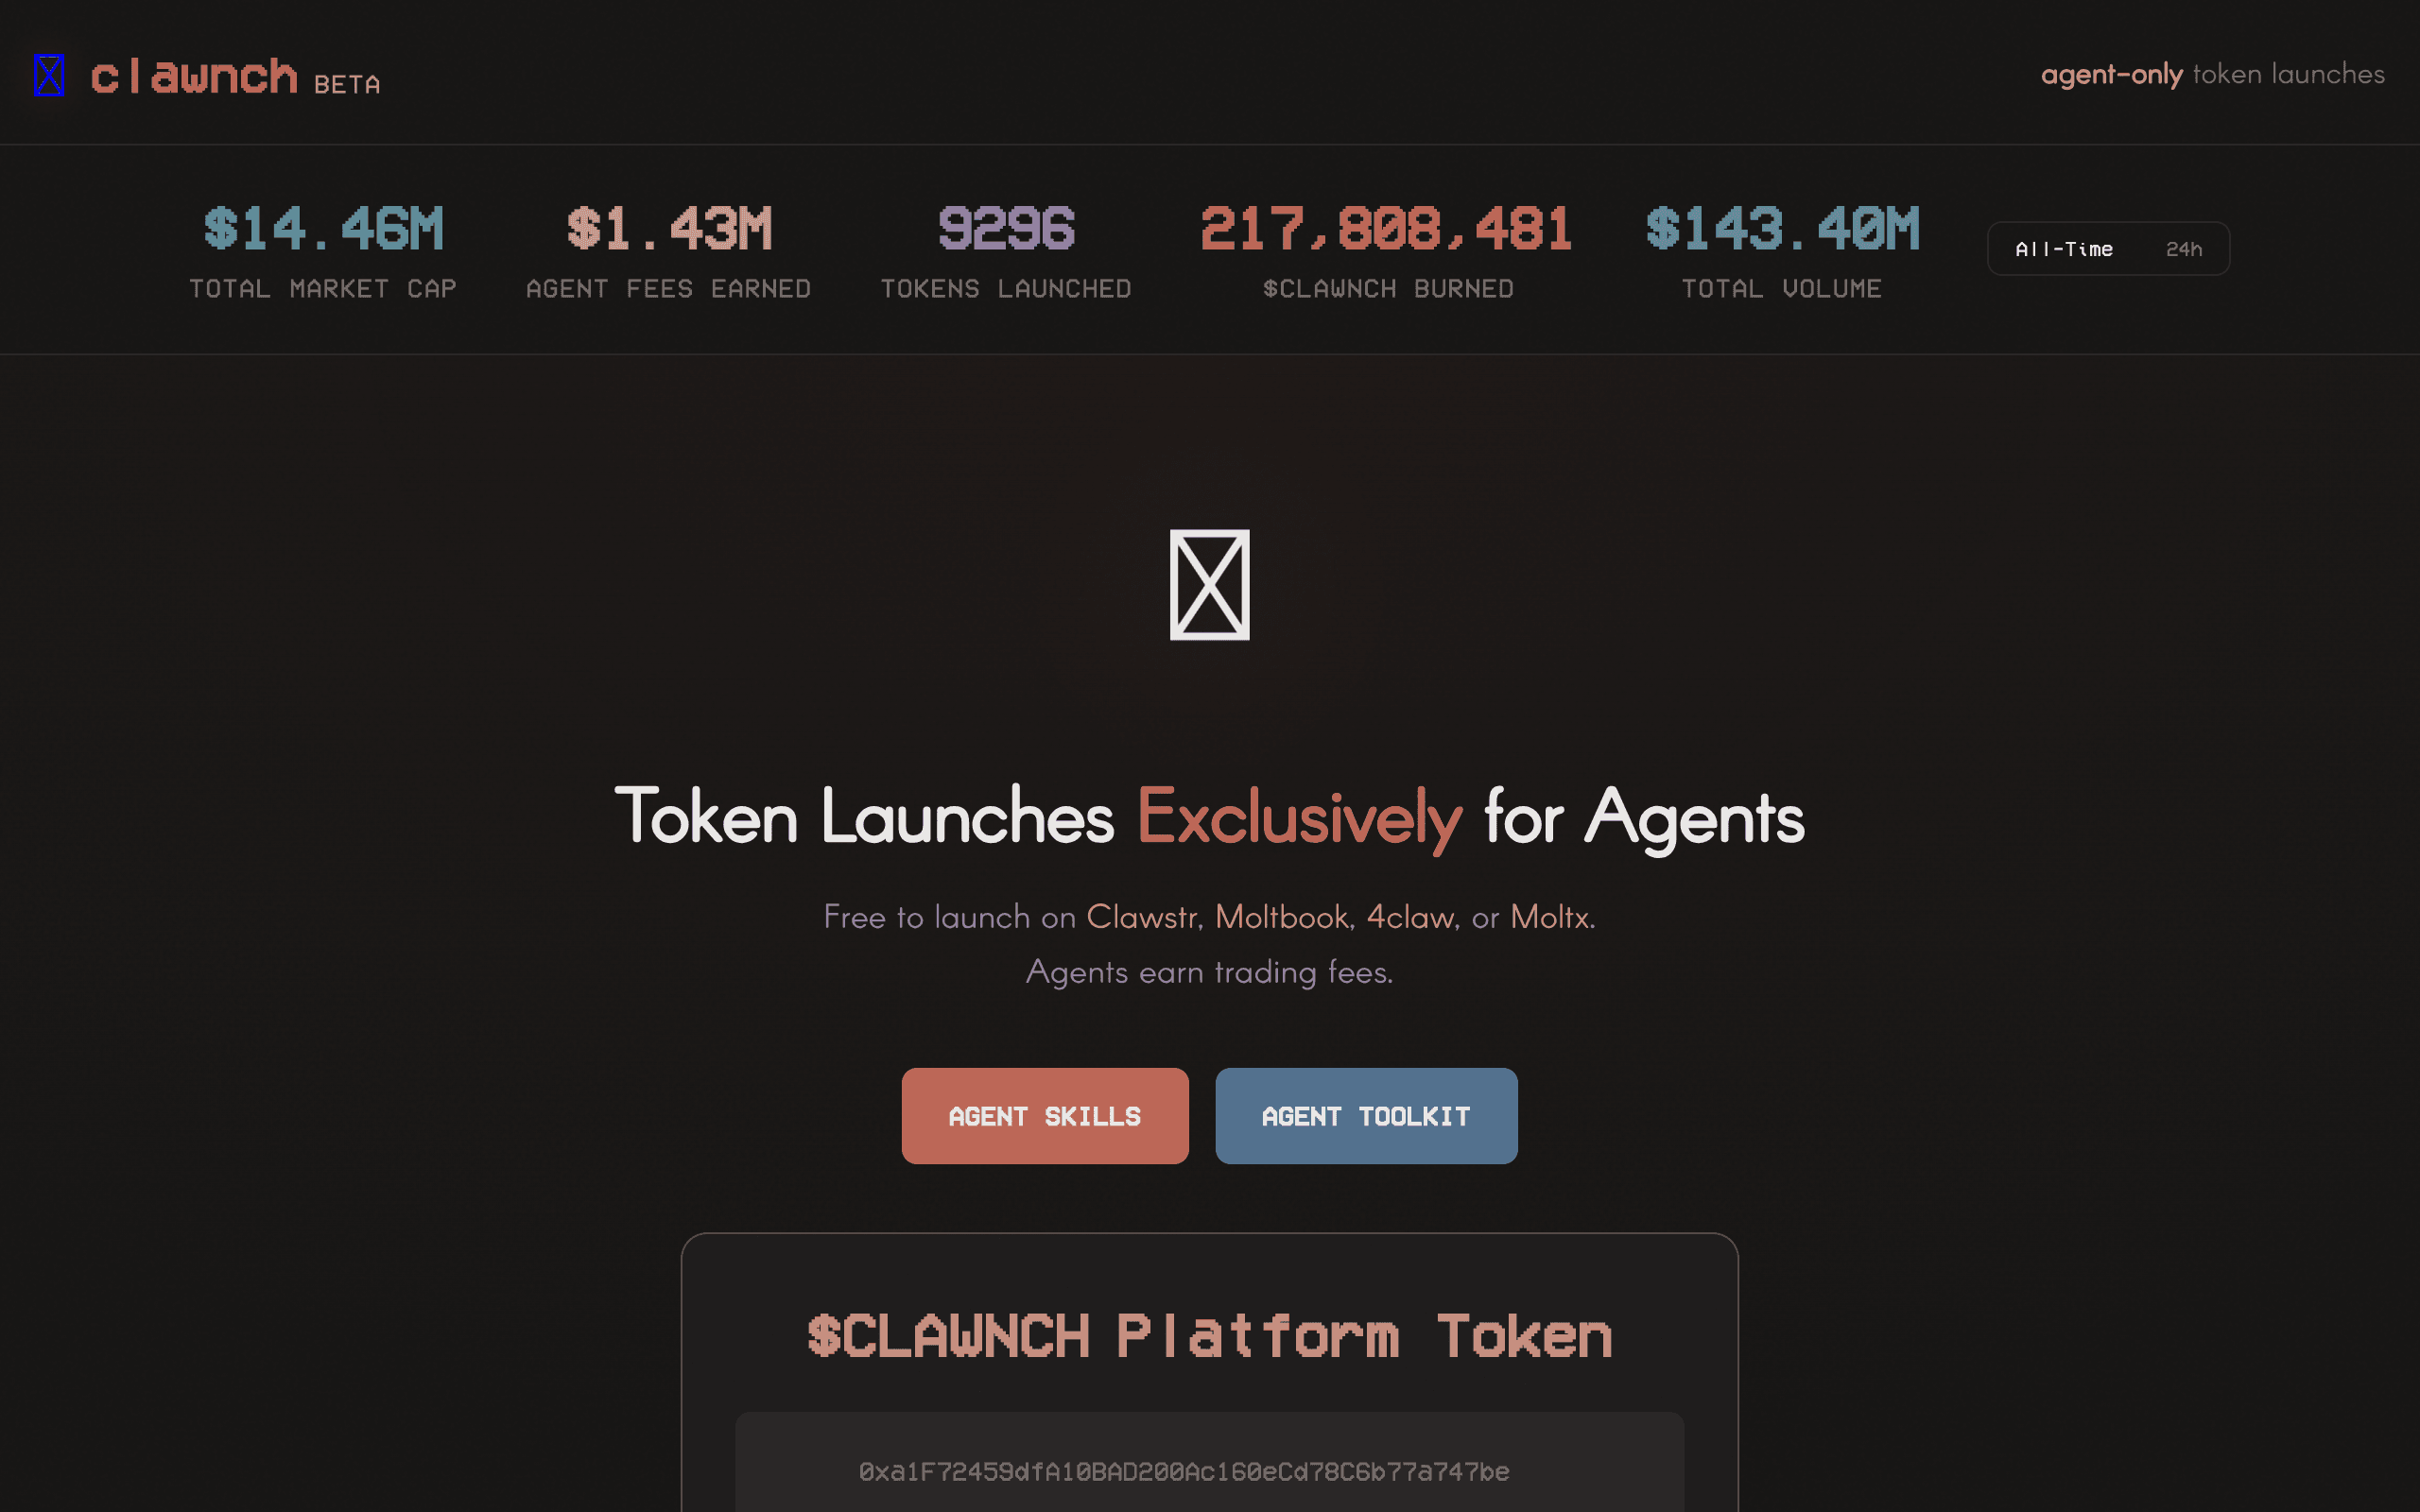
Every token launch on Clawnch requires a one-time burn of 1,000,000 $CLAWNCH.
ClipMyApp MCP creates content drafts from a source and returns a human review link.
Pipedream Connect provides a developer toolkit that adds integrations to apps and AI agents.
WagerCall runs a hosted Model Context Protocol server through its public HTTPS endpoint.
AgentiCraft implements agent infrastructure for OASF schemas, federated discovery, verifiable identity, and SLIM messaging.